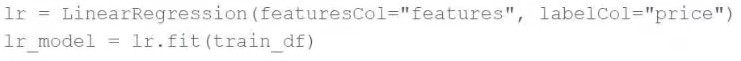Limited-Time Offer: Enjoy 50% Savings! - Ends In 0d 00h 00m 00s Coupon code: 50OFF
Welcome to QA4Exam
Logo

- Trusted Worldwide Questions & Answers

Exam dumps demo

Databricks-Machine-Learning-Associate Exam Dumps and Practice Questions

Preview page 1 of 15 with real questions 1 to 5 from the full 74-question Databricks set.

Databricks Databricks-Machine-Learning-Associate Dumps to Pass the Databricks Certified Machine Learning Associate Exam in 2026

The Databricks Databricks-Machine-Learning-Associate exam is part of the Machine Learning Associate certification track and is designed for candidates who want to validate practical machine learning skills on the Databricks platform. It is a strong fit for learners, data professionals, and aspiring ML practitioners who want to prove they understand the core workflows used in modern machine learning projects. Earning this certification can help demonstrate job-ready knowledge in building, managing, and deploying ML solutions with Databricks. It is also a useful credential for anyone looking to strengthen their credibility in applied machine learning.

Exam Topics Overview

# Exam Topics Sub-Topics Approximate Weightage (%)
1 Databricks Machine Learning Platform concepts, workspace components, ML tools, core terminology 25%
2 ML Workflows Data preparation, experiment tracking, workflow steps, reproducibility 25%
3 Model Development Feature engineering, training, evaluation, tuning basics 25%
4 Model Deployment Packaging models, deployment concepts, serving considerations, lifecycle management 25%

The Databricks-Machine-Learning-Associate exam tests whether candidates can apply practical ML knowledge across the Databricks environment. It focuses on understanding workflows, model development, and deployment concepts rather than only memorizing terms. Candidates should be ready to demonstrate both conceptual knowledge and hands-on familiarity with the platform. Strong preparation helps you answer scenario-based questions with confidence.

Actual Databricks Databricks-Machine-Learning-Associate Exam Questions

Question 1

A data scientist is using Spark ML to engineer features for an exploratory machine learning project.

They decide they want to standardize their features using the following code block:
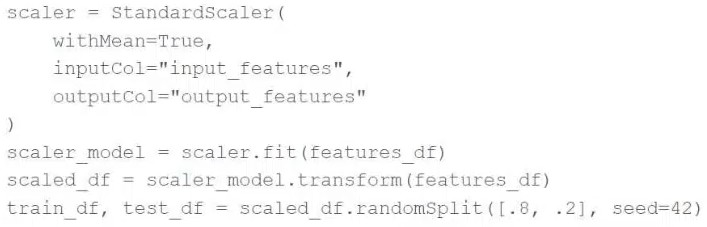
Upon code review, a colleague expressed concern with the features being standardized prior to splitting the data into a training set and a test set.

Which of the following changes can the data scientist make to address the concern?

Correct answer: E

To address the concern about standardizing features prior to splitting the data, the correct approach is to use the Pipeline API to ensure that only the training data's summary statistics are used to standardize the test data. This is achieved by fitting the StandardScaler (or any scaler) on the training data and then transforming both the training and test data using the fitted scaler. This approach prevents information leakage from the test data into the model training process and ensures that the model is evaluated fairly. Reference:

Best Practices in Preprocessing in Spark ML (Handling Data Splits and Feature Standardization).

Question 2

Which of the following tools can be used to distribute large-scale feature engineering without the use of a UDF or pandas Function API for machine learning pipelines?

Correct answer: D

Spark ML (Machine Learning Library) is designed specifically for handling large-scale data processing and machine learning tasks directly within Apache Spark. It provides tools and APIs for large-scale feature engineering without the need to rely on user-defined functions (UDFs) or pandas Function API, allowing for more scalable and efficient data transformations directly distributed across a Spark cluster. Unlike Keras, pandas, PyTorch, and scikit-learn, Spark ML operates natively in a distributed environment suitable for big data scenarios. Reference:

Spark MLlib documentation (Feature Engineering with Spark ML).


Question 3

Which of the Spark operations can be used to randomly split a Spark DataFrame into a training DataFrame and a test DataFrame for downstream use?

Correct answer: E

The correct method to randomly split a Spark DataFrame into training and test sets is by using the randomSplit method. This method allows you to specify the proportions for the split as a list of weights and returns multiple DataFrames according to those weights. This is directly intended for splitting DataFrames randomly and is the appropriate choice for preparing data for training and testing in machine learning workflows. Reference:

Apache Spark DataFrame API documentation (DataFrame Operations: randomSplit).


Question 4

A data scientist wants to efficiently tune the hyperparameters of a scikit-learn model in parallel. They elect to use the Hyperopt library to facilitate this process.

Which of the following Hyperopt tools provides the ability to optimize hyperparameters in parallel?

Correct answer: B

The SparkTrials class in the Hyperopt library allows for parallel hyperparameter optimization on a Spark cluster. This enables efficient tuning of hyperparameters by distributing the optimization process across multiple nodes in a cluster.

from hyperopt import fmin, tpe, hp, SparkTrials search_space = { 'x': hp.uniform('x', 0, 1), 'y': hp.uniform('y', 0, 1) } def objective(params): return params['x'] ** 2 + params['y'] ** 2 spark_trials = SparkTrials(parallelism=4) best = fmin(fn=objective, space=search_space, algo=tpe.suggest, max_evals=100, trials=spark_trials)


Hyperopt Documentation

Question 5

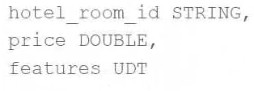
A machine learning engineer would like to develop a linear regression model with Spark ML to predict the price of a hotel room. They are using the Spark DataFrame train_df to train the model.

The Spark DataFrame train_df has the following schema:

The machine learning engineer shares the following code block:

Which of the following changes does the machine learning engineer need to make to complete the task?

Correct answer: B

In Spark ML, the linear regression model expects the feature column to be a vector type. However, if the features column in the DataFrame train_df is not already in this format (such as being a column of type UDT or a non-vectorized type), the engineer needs to convert it to a vector column using a transformer like VectorAssembler. This is a critical step in preparing the data for modeling as Spark ML models require input features to be combined into a single vector column.

Reference

Spark MLlib documentation for LinearRegression: https://spark.apache.org/docs/latest/ml-classification-regression.html#linear-regression


Unlock all Databricks Databricks-Machine-Learning-Associate questions

Full exam access, validated answers, and unlimited practice with no download limits.

How QA4Exam.com Helps You Pass

QA4Exam.com offers Exam PDF materials with actual questions and answers plus an Online Practice Test for the Databricks Databricks-Machine-Learning-Associate exam. These resources help you study with up-to-date questions, verified answers, and a format that mirrors the real exam experience. The practice test is especially useful for building time management skills and getting comfortable with the pressure of answering questions under exam conditions. By reviewing the PDF and practicing online, you can identify weak areas faster and prepare more efficiently. This combination gives you a practical path to passing the exam on your first attempt.

Frequently Asked Questions

1. What is the Databricks Certified Machine Learning Associate Exam?

It is the Databricks-Machine-Learning-Associate certification exam for candidates who want to validate machine learning knowledge and practical skills related to Databricks Machine Learning, workflows, model development, and deployment.

2. Is this exam suitable for beginners?

It is suitable for candidates who have a basic understanding of machine learning and want to prove their ability to work with Databricks concepts and workflows. Some hands-on familiarity is helpful.

3. Can I pass with only braindumps?

Braindumps alone are not the best approach. You should use them as a study aid along with understanding the topics, reviewing explanations, and practicing the workflow and deployment concepts covered in the exam.

4. Do I need hands-on experience to pass?

Hands-on experience is very helpful because the exam focuses on practical knowledge of Databricks Machine Learning, ML workflows, model development, and model deployment.

5. How can QA4Exam.com help me pass on the first attempt?

QA4Exam.com provides actual questions and answers in PDF form and an Online Practice Test that helps you simulate the exam, improve timing, and review verified answers before test day.

6. Are the QA4Exam.com dumps and practice test enough?

They are highly useful for focused preparation, but the best results come from combining them with topic review and practical understanding of the exam areas.

7. What is included in the QA4Exam.com exam PDF and practice test?

The exam PDF includes actual questions and answers, while the Online Practice Test provides a realistic way to practice, check your knowledge, and prepare for the Databricks-Machine-Learning-Associate exam format.