
Limited-Time Offer: Enjoy 50% Savings! - Ends In 0d 00h 00m 00s Coupon code: 50OFF
Welcome to QA4Exam
Logo

- Trusted Worldwide Questions & Answers

Exam dumps demo

DEA-C01 Exam Dumps and Practice Questions

Preview page 1 of 60 with real questions 1 to 5 from the full 302-question Amazon set.

Snowflake DEA-C01 Dumps - Pass SnowPro Advanced: Data Engineer Certification Exam in First Attempt 2026

The Snowflake DEA-C01 - SnowPro Advanced: Data Engineer Certification Exam is part of the SnowPro Certification and SnowPro Advanced Certification track. It is designed for data professionals who work with Snowflake and want to validate advanced skills in data engineering, operations, governance, and transformation. Earning this certification shows that you can handle real-world Snowflake workloads with confidence and accuracy. For candidates building a strong career in modern cloud data platforms, this exam is an important benchmark.

# Exam Topics Sub-Topics Approximate Weightage (%)
1 Data Ingestion and Transformation Bulk loading and continuous loading, Snowpipe and staged files, data transformation workflows 30%
2 Data Store Management Tables and views, storage structures and optimization, metadata and object lifecycle 25%
3 Data Operations and Support Monitoring and troubleshooting, query performance analysis, job scheduling and operational support 20%
4 Data Security and Governance Access control and roles, masking and policy management, governance and compliance controls 25%

The DEA-C01 exam tests more than memorization. It checks whether candidates can apply Snowflake knowledge in practical scenarios, solve data engineering problems, and make correct operational decisions. You need a solid understanding of ingestion, storage, security, and support concepts, along with the ability to choose the right approach under exam conditions.

Actual Amazon DEA-C01 Exam Questions

Question 1

A company wants to use Apache Spark jobs that run on an Amazon EMR cluster to process streaming data. The Spark jobs will transform and store the data in an Amazon S3 bucket. The company will use Amazon Athena to perform analysis.

The company needs to optimize the data format for analytical queries.

Which solutions will meet these requirements with the SHORTEST query times? (Select TWO.)

Correct answer: B, D

For high-performance analytics in Athena and EMR Spark, the columnar storage formats Parquet and ORC deliver the shortest query times. These formats minimize I/O, enable predicate pushdown, and support efficient compression and parallel reads.

When integrated with the AWS Glue Data Catalog, schema evolution is automatically tracked and managed across queries.

This combination (Parquet/ORC + Glue Catalog) is explicitly recommended by AWS for analytical workloads on S3 data lakes.

''For analytical workloads using Amazon EMR and Athena, store data in columnar formats such as Parquet or ORC. These formats provide optimized compression and query performance.''

-- Ace the AWS Certified Data Engineer -- Associate Certification -- version 2 -- apple.pdf

''Use the AWS Glue Data Catalog to manage table schemas and schema evolution for columnar data formats such as Parquet and ORC.''

-- Ace the AWS Certified Data Engineer -- Associate Certification -- version 2 -- apple.pdf

Therefore, using ORC or Parquet along with the Glue Data Catalog achieves the shortest Athena query times and seamless schema management.

Question 2

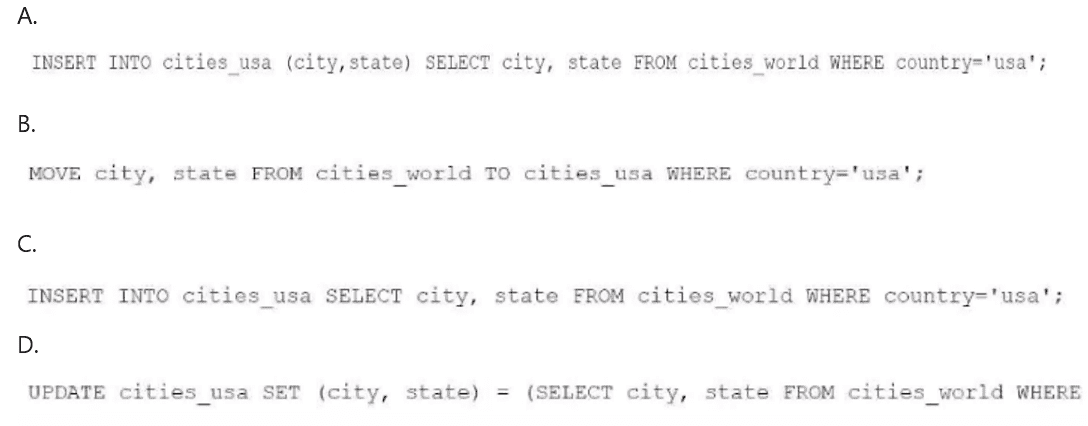
A data engineer needs to create an Amazon Athena table based on a subset of data from an existing Athena table named cities_world. The cities_world table contains cities that are located around the world. The data engineer must create a new table named cities_us to contain only the cities from cities_world that are located in the US.

Which SQL statement should the data engineer use to meet this requirement?

Correct answer: A

To create a new table named cities_usa in Amazon Athena based on a subset of data from the existing cities_world table, you should use an INSERT INTO statement combined with a SELECT statement to filter only the records where the country is 'usa'. The correct SQL syntax would be:

Option A: INSERT INTO cities_usa (city, state) SELECT city, state FROM cities_world WHERE country='usa';This statement inserts only the cities and states where the country column has a value of 'usa' from the cities_world table into the cities_usa table. This is a correct approach to create a new table with data filtered from an existing table in Athena.

Options B, C, and D are incorrect due to syntax errors or incorrect SQL usage (e.g., the MOVE command or the use of UPDATE in a non-relevant context).


Amazon Athena SQL Reference

Creating Tables in Athena

Question 3

A data engineer has two datasets that contain sales information for multiple cities and states. One dataset is named reference, and the other dataset is named primary.

The data engineer needs a solution to determine whether a specific set of values in the city and state columns of the primary dataset exactly match the same specific values in the reference dataset. The data engineer wants to use Data Quality Definition Language (DQDL) rules in an AWS Glue Data Quality job.

Which rule will meet these requirements?

Correct answer: A

The DatasetMatch rule in DQDL checks for full value equivalence between mapped fields. A value of 1.0 indicates a 100% match. The correct syntax and metric for an exact match scenario are:

''Use DatasetMatch when comparing mapped fields between two datasets. The comparison score of 1.0 confirms a perfect match.''

-- Ace the AWS Certified Data Engineer - Associate Certification - version 2 - apple.pdf

Options with ''100'' use incorrect syntax since DQDL uses floating-point scores (e.g., 1.0, 0.95), not percentages.


Question 4

A company has three subsidiaries. Each subsidiary uses a different data warehousing solution. The first subsidiary hosts its data warehouse in Amazon Redshift. The second subsidiary uses Teradata Vantage on AWS. The third subsidiary uses Google BigQuery.

The company wants to aggregate all the data into a central Amazon S3 data lake. The company wants to use Apache Iceberg as the table format.

A data engineer needs to build a new pipeline to connect to all the data sources, run transformations by using each source engine, join the data, and write the data to Iceberg.

Which solution will meet these requirements with the LEAST operational effort?

Correct answer: B

Amazon Athena provides federated query connectors that allow querying multiple data sources, such as Amazon Redshift, Teradata, and Google BigQuery, without needing to extract the data from the original source. This solution is optimal because it offers the least operational effort by avoiding complex data movement and transformation processes.

Amazon Athena Federated Queries:

Athena's federated queries allow direct querying of data stored across multiple sources, including Amazon Redshift, Teradata, and BigQuery. With Athena's support for Apache Iceberg, the company can easily run a Merge operation on the Iceberg table.

The solution reduces complexity by centralizing the query execution and transformation process in Athena using SQL queries.


Alternatives Considered:

A (AWS Glue pipeline): This would work but requires more operational effort to manage and transform the data in AWS Glue.

C (Amazon EMR): Using EMR and writing PySpark code introduces more operational overhead and complexity compared to a SQL-based solution in Athena.

D (Amazon AppFlow): AppFlow is more suitable for transferring data between services but is not as efficient for transformations and joins as Athena federated queries.

Amazon Athena Documentation

Federated Queries in Amazon Athena

Question 5

A company stores petabytes of data in thousands of Amazon S3 buckets in the S3 Standard storage class. The data supports analytics workloads that have unpredictable and variable data access patterns.

The company does not access some data for months. However, the company must be able to retrieve all data within milliseconds. The company needs to optimize S3 storage costs.

Which solution will meet these requirements with the LEAST operational overhead?

Correct answer: D

S3 Intelligent-Tiering is a storage class that automatically moves objects between four access tiers based on the changing access patterns. The default access tier consists of two tiers: Frequent Access and Infrequent Access. Objects in the Frequent Access tier have the same performance and availability as S3 Standard, while objects in the Infrequent Access tier have the same performance and availability as S3 Standard-IA. S3 Intelligent-Tiering monitors the access patterns of each object and moves them between the tiers accordingly, without any operational overhead or retrieval fees. This solution can optimize S3 storage costs for data with unpredictable and variable access patterns, while ensuring millisecond latency for data retrieval. The other solutions are not optimal or relevant for this requirement. Using S3 Storage Lens standard metrics and activity metrics can provide insights into the storage usage and access patterns, but they do not automate the data movement between storage classes. Creating S3 Lifecycle policies for the S3 buckets can move objects to more cost-optimized storage classes, but they require manual configuration and maintenance, and they may incur retrieval fees for data that is accessed unexpectedly. Activating the Deep Archive Access tier for S3 Intelligent-Tiering can further reduce the storage costs for data that is rarely accessed, but it also increases the retrieval time to 12 hours, which does not meet the requirement of millisecond latency.Reference:

S3 Intelligent-Tiering

S3 Storage Lens

S3 Lifecycle policies

[AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide]


Unlock all Amazon DEA-C01 questions

Full exam access, validated answers, and unlimited practice with no download limits.

How QA4Exam.com Helps You Pass

QA4Exam.com offers Exam PDF and Online Practice Test materials that are built to support focused DEA-C01 preparation. The PDF gives you actual questions and answers in a convenient study format, while the practice test helps you experience real exam simulation before test day. With up-to-date questions and verified answers, you can review the most relevant exam patterns and reduce surprises. The Online Practice Test also helps you practice time management so you can answer more confidently within the exam duration. Together, these resources are designed to improve readiness and help you aim for a first attempt pass.

Frequently Asked Questions

1. Who should take the Snowflake DEA-C01 exam?

This exam is intended for data engineers and Snowflake users who want to validate advanced knowledge across ingestion, storage, operations, and governance.

2. Is the Snowflake SnowPro Advanced: Data Engineer Certification Exam difficult?

Yes, it is an advanced-level exam that requires practical understanding, not just theory. Candidates should be comfortable with real Snowflake scenarios and concepts.

3. Can I pass DEA-C01 with only braindumps?

Braindumps alone are not enough. You should use them with hands-on practice and topic review so you understand why each answer is correct.

4. Do I need hands-on experience with Snowflake?

Hands-on experience is strongly recommended because the exam focuses on practical data engineering tasks and real operational decisions.

5. Are QA4Exam.com dumps and practice tests enough to prepare?

They are strong preparation tools, especially when combined with topic study and practical review. The Exam PDF and Online Practice Test help you focus on exam-style questions and answer patterns.

6. How do the QA4Exam.com practice test and PDF format help with first attempt success?

The practice test builds familiarity with exam timing and question style, while the PDF supports quick revision of questions and answers. This combination helps you prepare more efficiently for first attempt success.

7. Are the questions on QA4Exam.com updated for the DEA-C01 exam?

QA4Exam.com provides up-to-date questions and verified answers so you can study with current exam-oriented material.